Frontier Board
Every benchmark people actually watch.
The leaderboards behind the headlines: who runs them, what they test, who's on top right now, and what each model costs. Click any card to go to the source.
Scores refreshed 15 Oct 2026
Artificial Analysis
by Artificial Analysis
Intelligence Index built from 10 hard evals, plus price, speed and latency for every API model.
- 1Claude Opus 5.558
- 2Claude Sonnet 5.556
- 3Muse Wonder Full56
- Artificial Analysis Intelligence Index · top 3 of 54 current models
BridgeBench
by BridgeMind
Rates frontier coding models on 9 axes: reasoning, front end, back end, one-shot, security, trust, efficiency, speed and cost.
- 1Claude Opus 5.5760
- 2GPT-6 Astra728
- 3Claude Fable 5.1689
- BridgeBench (overall) · top 3 of 29 current models
 Index
Epoch AI Benchmarking Hub
by Epoch AI
89 benchmarks and the Epoch Capabilities Index (ECI), with open data (CC BY 4.0).
- 1Claude Opus 5.5166.8
- 2GPT-6 Astra166.4
- 3GPT-6.1 Sol166.3
- Epoch Capabilities Index · top 3 of 81 current models
 Human votes
Arena (formerly LMArena)
by Arena
Blind head-to-head votes from real people. Elo for text, WebDev, vision and more.
Open the source for the live table.
Scale SEAL Leaderboards
by Scale AI
20+ private, expert-built evals: agentic coding, frontier reasoning, safety and more.
Open the source for the live table.
 Reasoning
Humanity's Last Exam
by CAIS & Scale AI
2,500 expert-written questions at the edge of human knowledge.
- 1GPT-6 Astra54.8%
- 2Claude Fable 5.146.5%
- 3Gemini 3.1 Pro46.4%
- Humanity's Last Exam · top 3 of 13 current models
 Reasoning
ARC Prize
by ARC Prize Foundation
ARC-AGI puzzles that are easy for people and hard for AI, scored against cost per task.
- 1GPT-6 Astra95.0%
- 2GPT-6.1 Sol94.2%
- 3Claude Opus 5.593.3%
- ARC-AGI-2 · top 3 of 44 current models
 Agents
Terminal-Bench
by Stanford & Laude Institute
Real tasks in a terminal: compiling, debugging, setting up servers, data work.
- 1GPT-5.584.7%
- 2GPT-5.481.8%
- 3Gemini 3.1 Pro80.2%
- Terminal-Bench · top 3 of 14 current models
SWE-bench
by Princeton & Stanford
Fix real GitHub issues in real Python repos. Verified is the human-checked subset.
- 1Claude Opus 4.783.5%
- 2Gemini 3.5 Flash79.3%
- 3Claude Opus 4.678.7%
- SWE-bench Verified · top 3 of 16 current models
OpenRouter Rankings
by OpenRouter
Which models developers actually pay for, ranked by tokens and spend.
Open the source for the live table.
Vellum LLM Leaderboard
by Vellum
Provider-reported and independent results on non-saturated benchmarks.
Open the source for the live table.
 Coding
Aider Leaderboards
by Aider
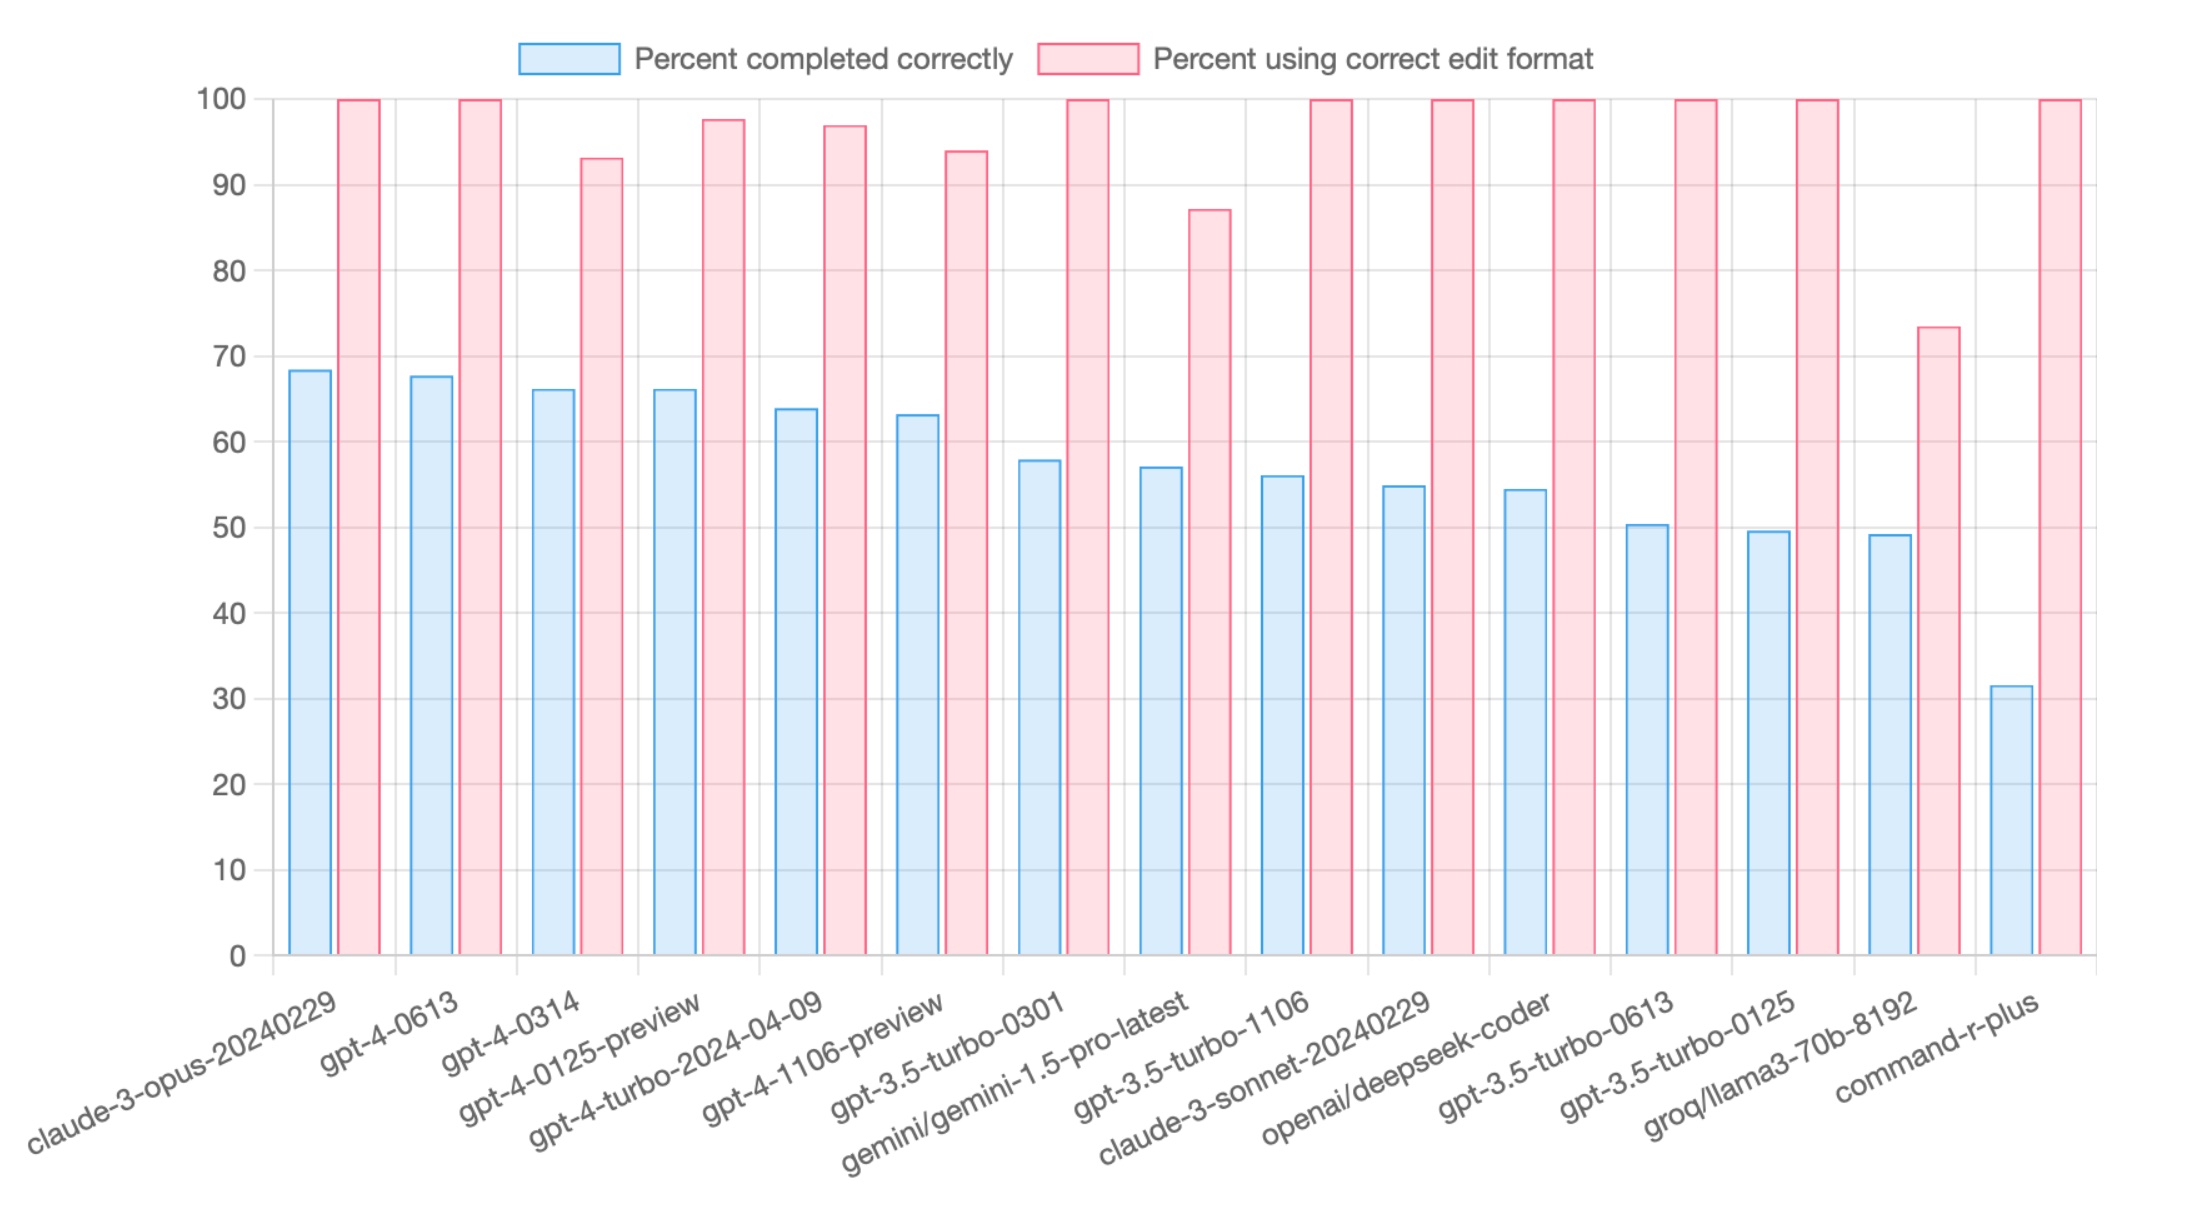
Polyglot code-editing across C++, Go, Java, JS, Python and Rust.
Open the source for the live table.
★Real use
The tests that are hard to game
Blind human votes, fresh tasks, private question sets and creators' own benchmarks. In B.O.B. these count double.
SimpleBench
AI Explained (YouTube)
Trick questions a person gets right and a pattern-matching model gets wrong.
- 1Claude Fable 581.9%
- 2Claude Opus 580.6%
- 3Gemini 3.1 Pro79.6%
- top 3 of 30 current models
BridgeBench (overall)
BridgeMind (YouTube)
A vibe-coding creator's own test suite, run on real app-building tasks.
- 1Claude Opus 5.5760
- 2GPT-6 Astra728
- 3Claude Fable 5.1689
- top 3 of 29 current models
LMArena Text
LMArena (blind human votes)
Real people compare two anonymous answers and pick the better one. Nothing to memorise.
- 1Gemini 4 Argon1525
- 2Muse Wonder1513
- 3Claude Opus 5.51508
- top 3 of 80 current models
LMArena Agent Arena
LMArena (real agent sessions)
Scored from real users' agent sessions: did the task get done, did it hallucinate tools.
- 1Claude Opus 5.50.170
- 2GPT-6.1 Sol0.150
- 3Claude Fable 5.10.143
- top 3 of 50 current models
LMArena WebDev
LMArena (blind human votes)
People ask for a real web app, compare two builds side by side and vote for the one that works better.
- 1Claude Opus 5.51811
- 2GPT-6 Astra1780
- 3Claude Sonnet 5.51774
- top 3 of 82 current models
LiveBench 2.0 (real-work suites)
LiveBench / Abacus.AI
Contamination-free real work: design, research, browser tasks, coding, long-running apps. Q&A suites left out.
- 1Claude Fable 5.188.8%
- 2Claude Opus 5.586.6%
- 3GPT-6 Astra85.5%
- top 3 of 39 current models
Vals Index
Vals AI (private test sets)
Independent evaluator with private test sets of paid work: finance, legal, tax, cyber.
- 1Gemini 4 Argon68.9%
- 2Claude Sonnet 5.567.0%
- 3Claude Opus 5.567.0%
- top 3 of 42 current models
SWE-rebench
Nebius
Fresh GitHub issues collected after each model's training cutoff.
- 1Claude Fable 564.5%
- 2Grok 4.563.8%
- 3Claude Opus 563.4%
- top 3 of 34 current models
Kagi LLM Benchmark
Kagi
Private question set that is never published, so it can't leak into training.
- 1Claude Fable 591.4%
- 2Claude Opus 4.888.8%
- 3GPT-5.588.8%
- top 3 of 22 current models
EQ-Bench Creative Writing
Sam Paech (open source)
Independent, open-source writing test that also penalises AI slop and repetition.
- 1GPT-6 Astra2173
- 2Claude Fable 5.12162
- 3Claude Opus 52133
- top 3 of 46 current models
SkateBench
Theo (t3.gg, YouTube)
A creator's niche knowledge test: 390 trick definitions, no lab optimises for it.
- 1Gemini 3.1 Pro97.0%
- 2GPT-5.482.0%
- 3GPT-5.4 Pro79.0%
- top 3 of 8 current models
What the top models cost
List prices per 1M tokens on OpenRouter for the 20 highest-ranked models, plus what Artificial Analysis spent per task to run its Intelligence Index. A model that thinks longer costs more per task, even at the same price.
- Claude Opus 5.5$4.00 / $20.00
- GPT-6 Astra$10.00 / $50.00
- Claude Fable 5.1$10.00 / $50.00
- Gemini 4 Argon$2.00 / $10.00
- GPT-6.1 Sol$2.00 / $10.00
- Claude Sonnet 5.5$2.00 / $10.00
- GPT-5.5 Pro$30.00 / $180.00
- Claude Fable 5$10.00 / $50.00
- Claude Opus 5$5.00 / $25.00
- GPT-6 Sol$2.00 / $10.00
- GPT-5.6 Sol Pro$4.00 / $20.00
- GPT-5.6 Sol$4.00 / $20.00
- MiMo-V2.6-Pro$0.43 / $0.87
- Muse Spark 1.3$1.25 / $4.25
- GPT-5.4 Pro$30.00 / $180.00
- GPT-5.5$5.00 / $30.00
- Claude Opus 4.8$5.00 / $25.00
- Gemini 3.8 Flash$0.75 / $3.75
- GPT-5.6 Terra$2.00 / $12.00
- Claude Haiku 5.5$0.10 / $0.50
- MiMo-V2.6-Pro$0.13
- Claude Haiku 5.5$0.21
- GPT-6.1 Sol$0.72
- Step 5 Preview$1.03
- Gemini 3.8 Flash$1.24
- GPT-5.6 Terra$1.40
- Muse Spark 1.3$1.60
- Gemini 4 Argon$1.99
- Kimi K3$2.00
- GLM-5.3$2.01
- GPT-6 Astra$3.26
- Grok 4.7$3.74
- Qwen3.8 Max$5.41
- Claude Sonnet 5.5$5.46
- Claude Opus 5.5$5.98
- Claude Fable 5.1$7.63
Source: Artificial Analysis, best setting per model.
Most score per dollar
Models with B.O.B. 60+, ranked by score ÷ blended price
- 1Claude Haiku 5.563 @ $0.20
- 2MiMo-V2.6-Pro76 @ $0.54
- 3Step 5 Preview62 @ $1.43
- 4Gemini 3.8 Flash64 @ $1.50
- 5Gemini 3.7 Flash62 @ $1.50
- 6Muse Spark 1.371 @ $2.00
Prices from OpenRouter list prices. Labs' direct prices, caching and batch discounts can be lower.